Human oversight sounds simple until volume rises. When review queues grow faster than attention can keep up, a human approval step can become procedural rather than meaningful. Oversight at scale therefore requires more than putting a person in the loop. It requires designing where judgment matters, how difficult cases are escalated, how the wider system is sampled, and whether reviewers have the evidence and authority needed to intervene.
View the complete figure here; open the full-size image for detail. On smaller screens, scroll the image horizontally.
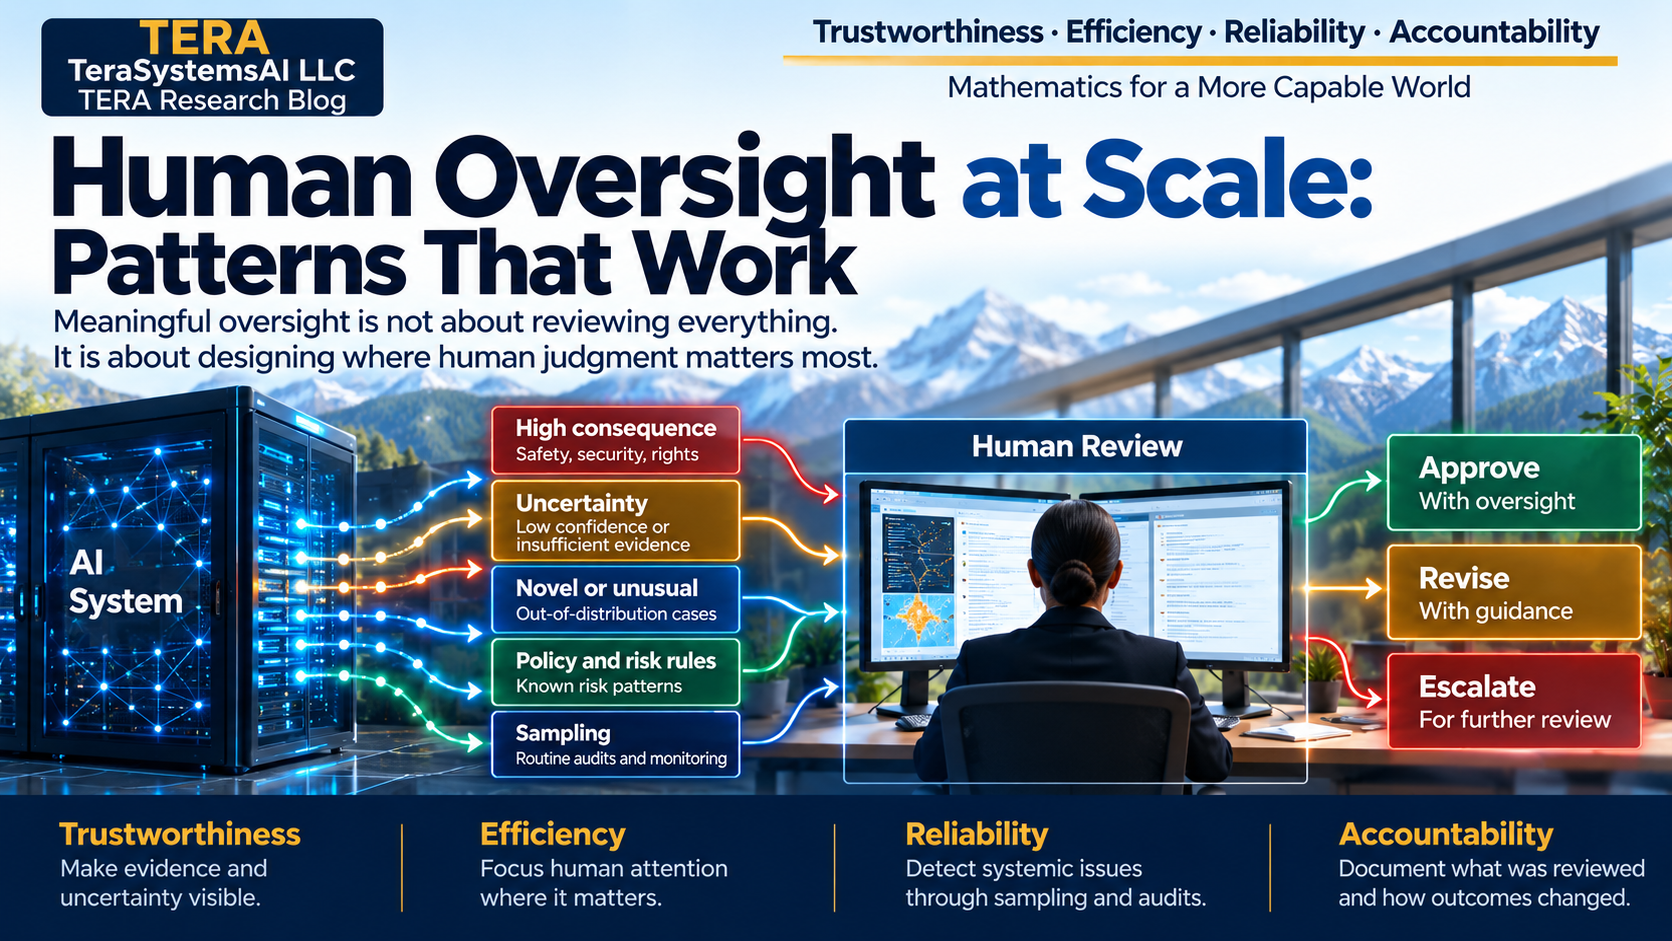
Key Takeaways
- Human review does not scale simply by assigning every output to a person.
- Oversight should concentrate attention according to consequence, uncertainty, novelty, and policy.
- Sampling and audits can reveal systemic problems that case-by-case review may miss.
- Reviewers need context, authority, and usable evidence, not only an approval button.
- The oversight process itself should be monitored for backlog, fatigue, disagreement, and ineffective intervention.
The ProblemOversight can collapse under volume
The intuitive approach to human oversight is to require someone to check every decision. That can work while volume is manageable. At higher throughput, the same design can become ineffective: queues grow, attention becomes fragmented, and reviewers may begin approving cases faster than meaningful judgment allows.
The system can still appear to contain human oversight while the practical value of that oversight has declined. The problem is therefore not simply the number of reviewers. It is the architecture of the review process.
A scalable system must decide which cases require direct intervention, which can receive lighter controls, and how the broader population will still be examined for patterns that individual reviewers cannot see.
Why It MattersHuman presence is not the same as human control
A human approval step does not automatically create meaningful oversight. Reviewers may lack sufficient information, have too little time, or be unable to override the system. Repeated exposure to apparently correct outputs can also make anomalies easier to miss.
The stronger question is:
Can the reviewer understand the case, challenge the system, and change the outcome when necessary?
Oversight should therefore be evaluated by what humans can actually do, not simply by whether a person appears somewhere in the workflow.
The TeraSystemsAI PerspectiveRoute attention where judgment can change outcomes
At TeraSystemsAI, we treat human oversight as a system-design problem. Human attention should be directed using several signals together: consequence of error, uncertainty or insufficient evidence, novelty, known failure modes, policy-triggered cases, disagreement, and deliberate random sampling.
Confidence alone should not determine whether a case receives review. A model can be confidently wrong.
Targeted review should also be complemented by sampling and auditing. Per-case escalation can identify individual problems. Sampling can reveal broader ones: drift, recurring error patterns, changes across populations, or failure modes that were not anticipated when the routing rules were designed.
Targeted intervention + systematic sampling + audit + escalation + feedback.
The objective is not for humans to inspect everything. It is to preserve meaningful human authority where intervention matters.
TERA applied to oversight
Practical ImplicationsRouting, sampling, authority, and feedback
A scalable oversight system should begin with consequence. High-consequence decisions may require mandatory review regardless of model confidence. Lower-risk cases may rely more heavily on automated controls, sampling, and post-deployment monitoring.
Routing should also identify uncertainty, unusual inputs, known risk patterns, and cases outside established operating conditions. Sampling remains important even when routing works well. Without it, a system can become blind to problems that its own escalation rules were never designed to detect.
Reviewers should receive enough context to make a real judgment: relevant evidence, model output, uncertainty where available, policy requirements, and the ability to inspect important supporting information.
They also need authority. A reviewer who can only approve, but cannot pause, reject, escalate, or request additional evidence, is not exercising meaningful control.
Finally, reviewer behavior should itself become evidence. Patterns in corrections, disagreements, escalations, and reversals can reveal where the underlying system or the oversight process needs improvement.
The Design PrincipleScale judgment, not rubber-stamping
Human oversight should not be measured by the number of outputs that pass in front of a person. It should be measured by whether human judgment remains capable of detecting problems, challenging automated decisions, and changing outcomes when necessary.
Route by consequence. Escalate uncertainty. Sample the whole system. Equip reviewers with evidence and authority. Monitor whether oversight still works.
TERA is applied, not advertised.